Agentic AI Malware: Why the Cybersecurity Battle Isn’t Over
Candid Wuest (Principal Security Advocate · xorlab)
BSides Las Vegas 2025 · Day 1
Overview
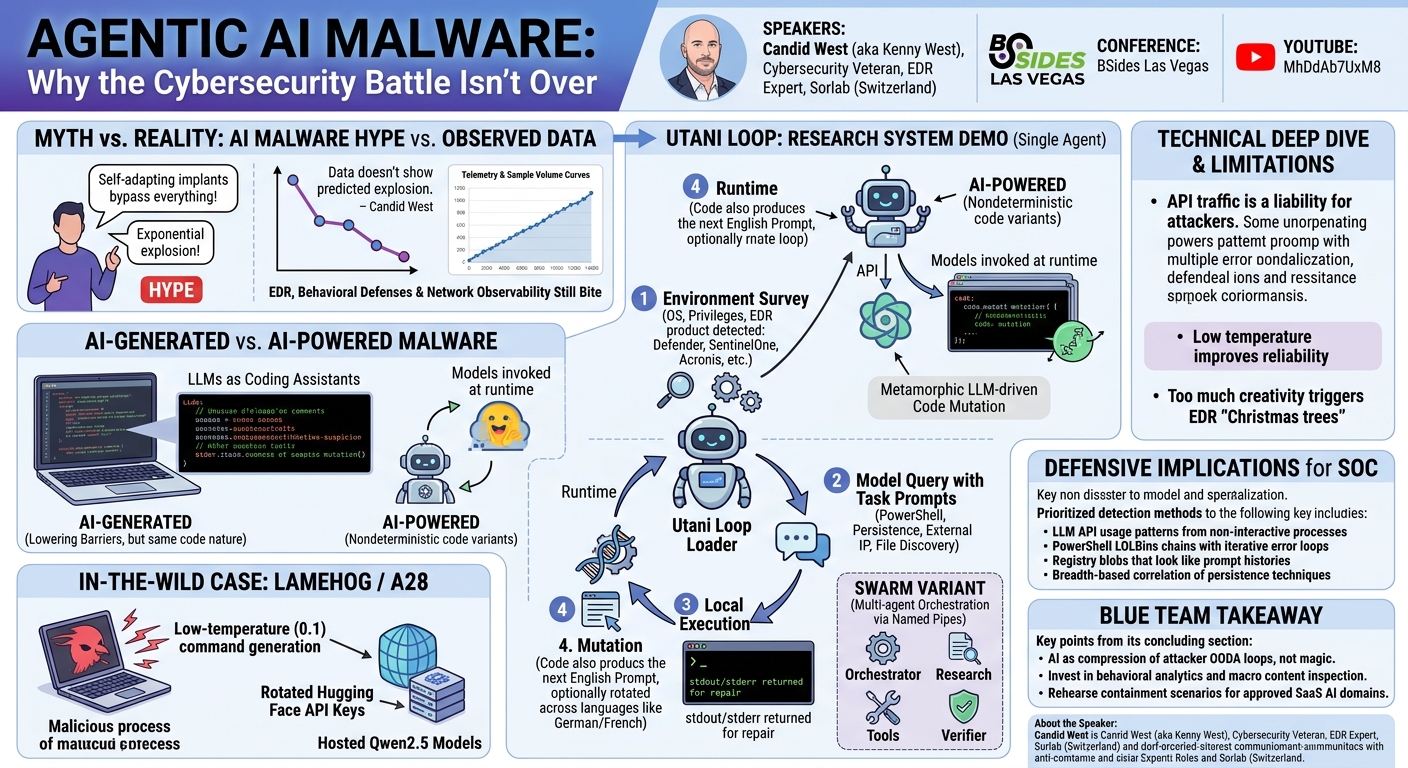
Candid West opens with a deliberately skeptical frame: headlines suggest agentic AI malware has ended the defensive game—self-adapting implants that bypass everything—yet telemetry and sample volume curves do not show the predicted explosion. The talk separates AI-generated malware (LLMs used as coding assistants) from AI-powered malware (models invoked at runtime), then walks examples of metamorphic LLM-driven code mutation, in-the-wild command generation (LameHog / A28 attribution discussed with Microsoft/OpenAI commentary), and a personal research system named Utani Loop that uses PowerShell, low-temperature sampling, registry prompt storage, and optional multi-agent orchestration via named pipes. The conclusion is measured: AI accelerates attacker iteration and planning, but behavioral defenses, network observability for LLM API traffic, and EDR maturity still bite—especially when implants get “creative” enough to touch half the MITRE matrix in a week.
Key moments
- 2:00 Speaker frames hype vs telemetry: where is the exponential growth of agentic AI malware if scanners predict doom?
- 4:00 AV-TEST-style sample volume chart narrative: post-ChatGPT monthly new samples remain roughly in the same band (~6M/month cited).
- 8:00 AI-generated malware examples: suspicious comments in scripts, underground claims, and analyst-tool prompt injection attempts.
- 14:00 Metamorphic LLM loop explained: stable English intent, nondeterministic generated PowerShell/Python, signature evasion tradeoffs.
- 18:00 Why breadth of LLM-chosen persistence techniques can increase behavioral detection surface for EDR.
- 20:00 LameHog case: low-temperature model use, many rotated API keys, Qwen2.5 on Hugging Face, Ukraine research attribution notes.
- 28:00 Utani Loop walkthrough: environment survey, registry-stored prompts, PowerShell execution loop with error repair.
- 34:00 Multi-agent orchestration via named pipes; verifier model; comparison to MCP-heavy academic pentest frameworks.
Agentic AI Malware: Why the Cybersecurity Battle Isn’t Over
Speakers: Candid West (introduced as Kenny West in opening; speaker states “Kenny West” in self-intro), cybersecurity practitioner and EDR veteran, currently with Sorlab (email security, Switzerland, as stated)
Conference: BSides Las Vegas
YouTube: https://www.youtube.com/watch?v=MhDdAb7UxM8
Overview
Candid West opens with a deliberately skeptical frame: headlines suggest agentic AI malware has ended the defensive game—self-adapting implants that bypass everything—yet telemetry and sample volume curves do not show the predicted explosion. The talk separates AI-generated malware (LLMs used as coding assistants) from AI-powered malware (models invoked at runtime), then walks examples of metamorphic LLM-driven code mutation, in-the-wild command generation (LameHog / A28 attribution discussed with Microsoft/OpenAI commentary), and a personal research system named Utani Loop that uses PowerShell, low-temperature sampling, registry prompt storage, and optional multi-agent orchestration via named pipes. The conclusion is measured: AI accelerates attacker iteration and planning, but behavioral defenses, network observability for LLM API traffic, and EDR maturity still bite—especially when implants get “creative” enough to touch half the MITRE matrix in a week.
The session blends threat intelligence vignettes, red-team humor, and live-demo video of Utani Loop generating persistence commands, external IP discovery, wallet searches, and self-mutating prompts. West also sketches future abuse paths—local models, stolen enterprise API keys, MCP poisoning, and IDE config implants—without claiming they are already dominant in telemetry.
Background
▶ Watch: Speaker frames hype vs telemetry: where is the exponential growth of agentic ... (2:00)
West positions himself as a long-time EDR builder (two EDR products referenced) now in email security at Sorlab. He contrasts AI phishing and deepfakes (other BSides talks) with malware specifically.
He cites AV-TEST-style sample throughput statistics (~6 million new samples/month around the ChatGPT inflection) to argue GenAI lowered barriers but did not step-change monthly novelty counts—acknowledging the unknown unknown problem for stealthy infostealers that may evade counting.
AI-generated malware examples include VBScript with unusual French comments (HP research cited), FunkSec group DOS scripts, and a Radamantis loader—where comments may signal LLM assistance, benign camouflage, or prompt-injection games against analysts. Checkpoint’s example of embedded “ignore previous instructions” text is shown as a sandbox/analysis evasion attempt that failed against tested scanners but illustrates the shape of coming analyst-tool attacks. Arrests are mentioned where ransomware authors allegedly used ChatGPT and Claude 2—proof of criminal use, not proof of dominance.
West also cites a Japanese case where ransomware was allegedly produced with LLM assistance in a few days—followed by arrest and a multi-year prison term mentioned in-session, underscoring legal risk even when generation is fast.
Stopwatch AI (as named) is held up as a cautionary toy: it will emit code for keyloggers/ransomware with vendor bypass labels, but output quality is not “nation-state grade.” The speaker’s point is epistemic—UI glitter does not equal operational capability.
West distinguishes AI-powered threats that embed runtime model use. Metamorphic malware here means repeated LLM calls generate nondeterministic code variants around a stable English intent (examples named include Black Mamba, Morph, Chatty Catty). He argues static signature bypass is not new; defenders should still catch downloaders, prompt carriers, and behavior.
To calibrate novelty, he compares LLM metamorphism to commodity builders and MaaS ecosystems that already mass-produce variants for tens of dollars in Monero—not identical to per-execution LLM mutation, but similar in signature pressure. He also cites historical modular state-associated toolchains (speaker references Red Gine and broader APT-style deployments in the transcript) that profile victims and fetch tailored modules—human-driven “reasoning” historically, now partially replaceable by models.
He references an OutFlake/BlackCat-linked research direction (timing described as “two days” from another conference) involving reinforcement learning over months to train a model that produces novel malware with improved Defender evasion rates—~8% success cited—immediately noting the multi-vendor problem: success against one stack does not generalize across CrowdStrike, SentinelOne, and others.
Key Findings
▶ Watch: AI-generated malware examples: suspicious comments in scripts, underground cl... (8:00)
1) “Undetected ≠ undetectable.” Ransomware-like outcomes remain constrained to a finite set of behaviors; encryption events are loud even if the dropper is fresh.
2) API traffic is a liability for attackers. Constant calls to ChatGPT/Gemini/Grok from endpoints should be rare in many enterprises; proxies and DLP programs already watch this. Attackers may pivot to self-hosted models or burned API keys cycling (LameHog used many Hugging Face keys, later blocked—per talk).
3) Low temperature improves reliability for adversaries. LameHog used temperature 0.1; West’s Utani Loop uses ~0.2 with ~20% command error rate—still noisy operationally.
4) Too much creativity triggers EDR “Christmas trees.” When an LLM cycles persistence across Run keys, services, DLL sideloading, etc., breadth of behaviors may outrun stealth.
5) Multi-agent orchestration is plausible but heavy. West demos orchestrator + research + tools + verification agents communicating via named pipes, with an explicit nod to Anthropic/university “In Calmo” framework using MCP and heavy tools like Mimikatz—which he avoids to reduce obvious telemetry.
6) EDR-specific “bypass plans” from LLMs often fail in practice. West shows Defender/CrowdStrike/SentinelOne tailored suggestions; by his testing, CrowdStrike and Sentinel plans were detected, Defender sometimes not—emphasizing non-transferable evasion and model knowledge cutoff effects.
7) Prompt engineering dominates outcomes. Role setting, goals, expected outputs, and iterative repair loops matter more than model branding.
Technical Deep Dive
▶ Watch: Why breadth of LLM-chosen persistence techniques can increase behavioral dete... (18:00)
Utani Loop architecture (single agent)
West describes a staged loader that retrieves encrypted prompts (e.g., from registry) to keep static surface small. Runtime steps:
- Environment survey: OS, privileges, observed security product (Defender, SentinelOne, Acronis, etc.—as enumerated in talk).
- Model query with task prompts: generate PowerShell for persistence, external IP, file discovery.
- Local execution with stdout/stderr returned into the loop for repair prompts when commands fail.
- Mutation: generated code also produces the next English prompt, optionally rotated across languages (German/French) to complicate static IOC hunting.
Exfiltration via model channels
West discusses encoding data into URL parameters for models to summarize—acknowledging mitigations where models refuse untrusted URLs, with workarounds mentioned at a high level (GitHub trust, paid tiers). This is presented as fragile and environment-dependent.
Swarm variant
Orchestrator consumes kill-chain/MITRE priors, assigns subtasks (persistence, credential access, exfiltration), monitors child agents, and pivots if processes die. Research agents propose targets (browser extensions, email stores). Tools agents compile PowerShell. A verifier model sanity-checks commands before execution—imperfect but adds depth.
Related work and events
West references DARPA AIxCC finalists, Google Project Zero “Big Sleep” 0-day research, a bug bounty talk citing large vulnerability counts (as named in-session), and LLM-backed C2 frameworks—mostly as existence proofs and future pressure.
Analysis toolchain attacks
Beyond endpoint malware, West sketches LLM integrations inside Ghidra/r2/IDA-class workflows where a poisoned sample might convince an assistant to mislabel malicious code—Whisper Code cited as a PoC class. The practical lesson is that AI in reverse engineering pipelines becomes a new trust boundary; defenders should not treat model summaries as ground truth without deterministic corroboration.
“Hack back” via owned inference (thought experiment)
Discussing LameHog’s reliance on hosted Qwen2.5-class code models on Hugging Face, West floats a thought experiment (explicitly not an endorsement): if a defender controlled the inference endpoint, they could return arbitrary commands to the implant. The segment is speculative ethics-wise but technically highlights supply-chain leverage points in API-mediated malware.
Agentic limitations called out in-session
West lists constraints that temper Skynet narratives: LLM size vs on-device execution (CPU/GPU load resembles mining), exfiltration volume if you ship terabytes to a model, difficulty knowing why a step failed when EDR kills an agent, and watchdog processes that merely double the detection surface. These are operational reasons A28-grade samples might remain sparse even as PoCs multiply.
Demo / Proof of Concept
▶ Watch: LameHog case: low-temperature model use, many rotated API keys, Qwen2.5 on Hu... (20:00)
A video shows Utani Loop running: persistence generation, registry prompt updates, Invoke-WebRequest for external IP, wallet file search with an initial underscore typo corrected after model blame-shifting (“copy/paste error”), and storage of refined prompts for later iterations. The demo is illustrative—not a field campaign.
Defensive Implications
▶ Watch: Multi-agent orchestration via named pipes; verifier model; comparison to MCP-... (34:00)
SOC detection should emphasize:
- LLM API usage patterns from non-interactive processes and servers.
- PowerShell LOLBins chains with iterative error/repair loops (unusual parent/child relationships, rapid mutation).
- Registry blobs that look like prompt histories or encoded tasking.
- Breadth-based correlation: many persistence techniques trialed sequentially.
Blue leadership should treat AI as compression of attacker OODA loops, not magic. Invest in behavioral analytics, macro content inspection for prompt carriers, and robust sandbox design aware of prompt injection against LLM-assisted reverse engineering plugins.
Red teams should note failure modes: error rates, API key burn, and telemetry from over-exploration.
Threat intel functions should track API key farming, Hugging Face account abuse, and corporate GenAI credentials on endpoints—because stolen enterprise keys recycle access as employees regain them after blocks.
Incident commanders should rehearse containment scenarios where an attacker uses approved SaaS AI domains: blocking may be politically hard, so detection must pair technical signals (non-interactive clients, odd OAuth flows, burst prompts) with policy clarity on acceptable use.
Key Takeaways
- Media hype outpaces observed agentic malware prevalence—so far.
- AI-generated and AI-powered malware are different defensive problems.
- Metamorphic LLM loops mainly stress static defenses; behavior still applies.
- LameHog-style command synthesis is a credible early in-the-wild shape of runtime model use.
- Utani Loop demonstrates planning automation more than unknowable super-malware.
- Multi-agent approaches add complexity and operational risk to attackers too.
- EDR outcomes remain vendor-specific; treat LLM “bypass recipes” skeptically.
About the Speaker(s)
The opening announcer introduces Candid West; the speaker’s self-introduction uses Kenny West, describing cybersecurity work since the late 1990s, EDR engineering background, and current role at Sorlab (Switzerland email security). The bundle metadata lists Speakers: Unknown; names are taken from the recording. Any spelling variations (Sorlab vs alternatives) follow the transcript.
Reviews
Dr. Zero (Offensive Security Researcher) — STRONG ACCEPT
A grounded debunking of agentic-malware hype with concrete threat taxonomy, real incident anchors, and a credible homemade multi-agent demo—exactly the sanity check this subfield needs.
Heather Calloway (CISO) — STRONG ACCEPT
The talk gives executives a usable mental model: generative AI mainly compresses attacker iteration and planning, which raises the premium on logging, acceptable-use policy, and vendor transparency—not magical new legal immunity for attackers.