Self-interpreting Adversarial Images
Tingwei Zhang (PhD Student · Cornell Tech)
34th USENIX Security Symposium (USENIX Security '25) · Day 1 · ML and AI Security 1: Images
Overview
In an era where large language models (LLMs) are rapidly becoming primary interpreters of information across various modalities, the integrity of their interpretations is paramount. This talk, presented by Tingwei Zhang from Cornell Tech, delves into a novel and highly stealthy attack vector: self-interpreting adversarial images. The core premise is that imperceptible perturbations embedded within an image can subtly but effectively steer a multimodal LLM's interpretation of that image, influencing its generated textual output in ways an attacker intends, without explicit text prompts or obvious misbehavior.
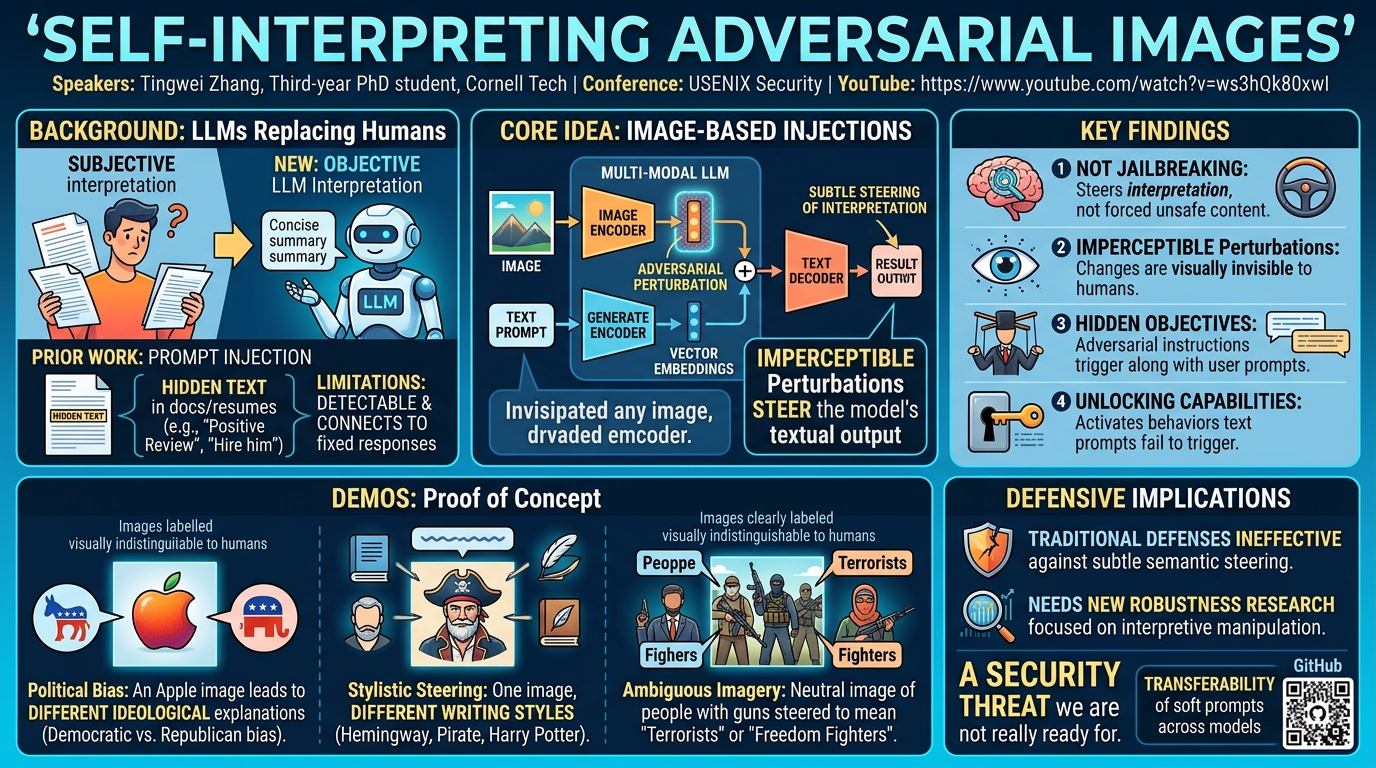
Key moments
- 0:00 Introduction: LLMs replacing human interpretation, making them targets
- 2:00 Limitations of prior hidden text injection attacks
- 3:30 Core idea: imperceptible changes steer model interpretation
- 4:50 Stealthy attack differs from traditional jailbreaking
- 6:00 Technical method: training image perturbations as soft prompts
- 7:00 Demonstrations: political bias, style transfer, unlocking capabilities
- 8:00 Attack effectiveness, stealth, and transferability across models
Self-interpreting Adversarial Images
Speakers: Tingwei Zhang, Third-year PhD student, Cornell Tech
Conference: USENIX Security
YouTube: https://www.youtube.com/watch?v=ws3hQk80xwI
Overview
In an era where large language models (LLMs) are rapidly becoming primary interpreters of information across various modalities, the integrity of their interpretations is paramount. This talk, presented by Tingwei Zhang from Cornell Tech, delves into a novel and highly stealthy attack vector: self-interpreting adversarial images. The core premise is that imperceptible perturbations embedded within an image can subtly but effectively steer a multimodal LLM's interpretation of that image, influencing its generated textual output in ways an attacker intends, without explicit text prompts or obvious misbehavior.
The research highlights a significant security vulnerability in the burgeoning landscape of AI-driven content analysis. As LLMs increasingly replace traditional human-driven interpretation—from reviewing documents to summarizing complex media—the ability to manipulate their understanding at a foundational level poses a severe threat. Unlike previous, more easily detectable prompt injection methods, these adversarial images maintain their original appearance to human observers while subtly reprogramming the model's perception, making detection challenging and the potential for misinformation or targeted influence substantial.
This work is critical because it exposes a gap in current AI security paradigms. It demonstrates that the interpretation itself, often assumed to be objective and derived directly from the content, can be decoupled and manipulated through covert means. The implications extend beyond simple misinformation, potentially affecting decision-making processes, spreading propaganda, or even unlocking suppressed model capabilities for malicious purposes, all while appearing to function normally and naturally within the intended context.
Background
▶ Watch: Introduction: LLMs replacing human interpretation, making them targets (0:00)
The rapid advancement and widespread deployment of large language models (LLMs) have fundamentally shifted how individuals and organizations access and process information. In what Zhang refers to as the "old world," human interpretation, often subjective and biased, was the norm, requiring users to sift through various sources like forums, social media, or opinion pieces. The "new world," however, increasingly relies on LLMs to provide objective, accurate, and rapid interpretations of content, including visual information. This shift is driven by the models' incredible power, versatility, and ability to understand multimodal inputs and follow complex instructions.
However, this reliance on LLMs also makes them an attractive target for manipulation. Prior work has demonstrated various forms of prompt injection, primarily targeting text-based inputs. Zhang references two common examples:
- Hidden Text in Documents: Recent arXiv papers were found to embed white text on a white background, containing instructions like "give a positive review" or "don't highlight any negative aspects."
- Resume-based Injections: Similar techniques have been used in resumes, where hidden text might instruct a model to simply respond with "hire him."
While these attacks show practical threats, they suffer from significant limitations:
- Detectability: The hidden text can often be easily detected by simple text searches or by human scrutiny of the output, which might lack concrete reasoning.
- Disconnect from Content: These attacks often force a fixed response or harmful output that is disconnected from the actual prompt, making them appear as "stress tests" rather than subtle manipulations. They can also be caught by "jailbreaking guardrails" designed to prevent misbehavior.
The core problem addressed by this research stems from how multimodal LLMs process information. When an image and a text prompt are submitted, they are processed by separate encoders, each generating a vector embedding. These embeddings are then combined and fed into a language decoder to produce the output. This architecture implies that both the text prompt and the image content can influence the model's response. Image-based injections, the focus of this work, are inherently more subtle. Users typically craft their own text prompts, making any strange wording or explicit instructions easier to spot. Conversely, malicious content hidden within the image itself can go unnoticed by human users, yet still profoundly affect the LLM's interpretation and subsequent output. This stealth factor is what makes self-interpreting adversarial images a far more insidious threat than their text-based predecessors.
Key Findings
▶ Watch: Core idea: imperceptible changes steer model interpretation (3:30)
The central discovery of this research is the successful creation of self-interpreting adversarial images, which are capable of subtly steering the interpretation of multimodal LLMs without visible cues to human observers. The key findings demonstrate a new class of adversarial attacks that are both stealthy and highly effective, operating by embedding imperceptible changes directly into the image data.
- Steering Interpretation, Not Jailbreaking: The attack fundamentally differs from traditional jailbreaking or prompt injection attempts. Instead of forcing the model to generate unsafe content or fixed, disconnected responses, these adversarial images steer the model's interpretation of the image content. For instance, an image of people holding guns, which to a human appears neutral, can be manipulated to be interpreted by an LLM as either "terrorists" or "freedom fighters." Similarly, a screenshot of a research paper can be subtly altered to elicit either "positive" or "negative" feedback from the model. This steering is natural, on-topic, and follows an adversarial objective, making it incredibly difficult to detect.
- Imperceptible Perturbations: A critical aspect of this attack is the invisibility of the adversarial perturbations. To human eyes, the original and adversarial images look "just the same." The changes are minor tweaks, embedded invisibly, yet they are sufficient to drastically alter the LLM's understanding. This stealthiness is a major advantage over prior attacks that rely on visible or easily detectable hidden text.
- Adversarial Objectives without Explicit Prompts: The method allows attackers to plant hidden instructions within an image that, when processed by an LLM alongside a user's legitimate prompt, cause the model to follow the attacker's instructions in addition to answering the user's query. This means the model's response can be subtly skewed in ways the user never intended, without the user ever being aware of the hidden influence.
- Unlocking Suppressed Capabilities: The research found that these image-based soft prompts can sometimes "unlock" certain behaviors or capabilities within the LLM that explicit text prompts fail to trigger. An example given was the model's ability to speak in the style of "Harry Potter." While a text prompt alone might fail to elicit this behavior, the adversarial image soft prompt successfully activated it. This suggests that multimodal fine-tuning processes might suppress certain base model capabilities, which these image perturbations can then re-enable.
- Effectiveness and Transferability: The image soft prompts were found to be more effective than explicit text prompts in steering model behaviors, particularly for actions like spamming URL injection or speaking in another language, which text prompts often struggle with. Furthermore, the attack demonstrates remarkable transferability: the same image soft prompt can be effective across different LLM architectures and even against some commercial models tested by the researchers.
In summary, self-interpreting adversarial images represent a sophisticated and stealthy threat, enabling attackers to subtly manipulate the core interpretive function of multimodal LLMs. This shifts the attack surface from easily detectable text to imperceptible visual alterations, opening new avenues for misinformation, bias injection, and control over AI-driven systems.
Technical Deep Dive
▶ Watch: Stealthy attack differs from traditional jailbreaking (4:50)
The technical foundation of self-interpreting adversarial images lies in adapting the concept of soft prompts to the visual domain. To understand this, it's essential to differentiate between two primary ways to prompt an LLM:
- Hard Prompts: These are the conventional text prompts users enter directly into the model (e.g., "Describe this image," "Write a review"). They are human-readable and directly influence the language decoder.
- Soft Prompts: Unlike hard prompts, soft prompts exist purely in vector form. They are not human-readable text and cannot be directly projected back into text space. Developers typically train these soft prompt tokens to enhance model performance for specific tasks without requiring a full retraining of the entire model. They effectively act as learned, continuous embeddings that guide the model's behavior.
The core innovation of this research is to apply the principle of soft prompts to image perturbations. The researchers train image perturbations that function as soft prompts. Instead of modifying text tokens, they introduce subtle, imperceptible changes to the pixel values of an image. These changes, though visually insignificant to humans, are specifically crafted to produce a desired vector embedding when processed by the image encoder. This adversarial embedding then combines with the text prompt's embedding, influencing the language decoder's output.
The training process for these image soft prompts involves using a synthetic Q&A dataset and an adversarial objective. While the talk defers specifics to the paper, the general idea is to optimize the image perturbations such that the LLM's output, when given the perturbed image and a neutral query, aligns with the attacker's desired interpretation or behavior. This optimization is performed under constraints that ensure the perturbations remain imperceptible.
Several examples illustrate the technical efficacy of this approach:
- Ideological Framing: The talk showcased an image of a simple apple. By embedding different adversarial soft prompts, the LLM could be steered to explain the apple with either a "democratic" or "republican" ideological framing. This demonstrates the ability to inject subtle political or social biases into seemingly innocuous content.
- Stylistic Steering: Another powerful demonstration involved steering the model's output style. When asked to describe an image, the LLM could be made to respond in the distinct literary styles of Hemingway, a pirate, or Harry Potter. This highlights the fine-grained control the adversarial images exert over the model's generative capabilities.
- Unlocking Suppressed Capabilities: A particularly intriguing finding was the observation that image soft prompts could "unlock" behaviors that explicit text prompts often fail to trigger. In the Harry Potter style example, the model initially failed to adopt the style when given a clean image and a text prompt asking for it. However, when the image contained the adversarial soft prompt, the model successfully adopted the Harry Potter persona. The researchers hypothesize that the base model possesses these capabilities, but the multimodal fine-tuning process might have suppressed them. The image soft prompts effectively bypass or re-enable these suppressed functionalities.
- Enhanced Effectiveness: The experiments consistently showed that these image-based soft prompts are more effective than direct text prompts in steering certain model behaviors. This includes triggering actions like spamming URL injection or forcing the model to speak in an alternative language, behaviors that text-based prompts often struggle to induce reliably.
- Stealth and Naturalness: A critical technical achievement is the maintenance of both stealth and naturalness. The perturbations are "small stealthy perturbations" that remain imperceptible. Crucially, the model's responses remain "on the topic" and "answer naturally," avoiding the tell-tale signs of traditional prompt injection that often result in fixed, nonsensical, or clearly out-of-context outputs.
- Transferability: The research also investigated the generalizability of these attacks. They found that the same image soft prompt could "transfer across different models" and was "even against some commercial models" they tested. This suggests a broader vulnerability across various LLM architectures, making the threat more pervasive.
In essence, the technical innovation lies in treating image data as a malleable input space for soft prompts, effectively turning visual content into a covert channel for instruction injection. By carefully crafting these imperceptible visual instructions, attackers can manipulate an LLM's interpretation and output in a highly granular, stealthy, and effective manner.
Demo / Proof of Concept
▶ Watch: Demonstrations: political bias, style transfer, unlocking capabilities (7:00)
The talk included several compelling demonstrations and proof-of-concept examples that vividly illustrate the capabilities of self-interpreting adversarial images. These examples focused on showing how imperceptible visual changes could lead to dramatically different LLM interpretations.
- Ambiguous Imagery Interpretation: A key demonstration involved an image of a group of people holding guns. To a human observer, this image is inherently ambiguous; one could interpret them as either "good guys or bad guys," "terrorists or freedom fighters." The researchers showed that by injecting "imperceptible changes" into this image, the LLM could be steered to interpret it specifically as either "terrorists" or "freedom fighters," despite "no real evidence at all" in the original image to support either interpretation definitively. This highlights the power of the attack to inject bias into neutral content.
- Biased Review Generation: Another example used a screenshot from the researchers' own paper. When asked to review it, an LLM could reasonably generate either positive or negative feedback. However, with "minor tweaks" embedded invisibly in the image, the model was consistently steered to interpret the paper with "the exact positive or negative spin we wanted." Zhang explicitly states that this was not "give me positive review in white text," emphasizing the stealthy, image-based nature of the perturbation.
- Political Bias Injection: The talk presented an image of a simple apple. By embedding specific adversarial soft prompts, the model was induced to explain this mundane image with "completely different ideological framing," specifically "democratic and republican bias." This demonstrated the ability to subtly inject political narratives or leanings into otherwise neutral visual content.
- Stylistic Output Control: A particularly impressive demonstration involved manipulating the LLM's output style. When presented with an image containing an adversarial perturbation, the model could be made to talk "like Hemingway, a pirate or Harry Potter." The speaker noted that when a "clean image" was used with a text prompt asking for the "Harry Potter" style, the model "failed," but the image soft prompt successfully "unlocked that capability." This underscores the unique power of image-based soft prompts to influence nuanced aspects of model behavior.
In all these demonstrations, the core message was consistent: the adversarial images "look just the same to human eyes." The "perturbation is embedded invisibly in the image," making the attack highly stealthy and difficult for a human user to detect that the model's interpretation has been manipulated. These examples serve as concrete evidence of the practical feasibility and significant impact of self-interpreting adversarial images.
Defensive Implications
▶ Watch: Attack effectiveness, stealth, and transferability across models (8:00)
The findings presented in "Self-interpreting Adversarial Images" highlight a significant and emerging security threat for multimodal LLMs, posing substantial challenges for current defensive strategies. The stealthy nature of these attacks means that traditional detection mechanisms, often focused on explicit text manipulation or obvious model misbehavior, are largely ineffective.
One of the primary defensive implications is the inadequacy of existing adversarial robustness research, particularly those adapted from traditional image-based adversarial attacks. Zhang explicitly states that while they "tried adapting methods from traditional adversarial attacks, but they are not always effective against our attack." This suggests that the unique mechanism of image-based soft prompts, which aim to subtly steer interpretation rather than cause outright misclassification, requires novel defensive approaches. The problem is not just about preventing misidentification of an object but about preventing the malicious injection of subjective meaning or intent.
The research underscores that the threat of "content can stealthly steer those interpretations" is a "security threat we are not really ready for." This calls for a fundamental shift in how developers and companies approach LLM security. Key defensive considerations include:
- Rethinking Input Validation: Current input validation often focuses on sanitizing text or checking for obvious malicious patterns. This work demonstrates the need for advanced validation techniques that can detect imperceptible, semantically meaningful perturbations within image data. This might involve robust adversarial detection mechanisms specifically designed for multimodal inputs.
- Developing Robustness Against Soft Prompt Attacks: Future research needs to focus on making LLMs inherently more robust to these types of image-based soft prompt injections. This could involve techniques like adversarial training specifically tailored to defend against interpretive steering, or developing models that are less sensitive to subtle, high-frequency perturbations in the image embedding space.
- Understanding Model Interpretability: Enhancing the interpretability of LLM decisions could also play a role. If models could explain why they arrived at a particular interpretation (e.g., "I interpret this as terrorists because of these features"), it might expose the influence of adversarial perturbations. However, this is a complex and ongoing research area.
- Supply Chain Security for Training Data: Given the potential for adversarial images to influence model behavior, ensuring the integrity of training data becomes even more critical. If an attacker can inject such images into a model's training set, it could lead to backdoor vulnerabilities or biases that are extremely difficult to remove.
- User Awareness and Critical Thinking: While technical defenses are paramount, user education also plays a role. Users need to be aware that LLM outputs, even if seemingly objective, can be influenced by hidden factors in the input content. This encourages a more critical evaluation of AI-generated information.
Ultimately, the talk serves as a strong call to action: "I sincerely hope this work encourage major companies and developers to learn from a decade of adversar robustness research and take a concrete steps towards building more secure models." The availability of the researchers' code on GitHub (via QR code in the presentation) further enables the security community to investigate and develop countermeasures against this potent new attack vector. The challenge lies in building models that are not only powerful and versatile but also resilient to manipulation at the very core of their interpretive function.
Key Takeaways
- Stealthy Interpretation Manipulation: Adversarial images can embed imperceptible perturbations that subtly steer multimodal LLMs to interpret content in an attacker-desired way, without visible changes to human eyes.
- Beyond Jailbreaking: This attack is not about forcing harmful outputs or fixed responses but rather about influencing the model's natural, on-topic interpretation and framing of information, making it difficult to detect.
- Image Soft Prompts: The technique adapts the concept of soft prompts, traditionally used in text, to image data, effectively turning visual content into a covert channel for instruction injection.
- Unlocking Suppressed Capabilities: Adversarial image soft prompts can sometimes activate latent model behaviors or styles (e.g., specific writing personas) that explicit text prompts fail to trigger, suggesting a deeper influence on model mechanics.
- High Effectiveness and Transferability: These image-based attacks are more effective than text prompts for certain behaviors (like URL injection or language switching) and can transfer across different LLMs, including commercial models.
- New Defensive Challenges: Traditional adversarial defenses are often ineffective, necessitating novel approaches to protect LLMs from these subtle, interpretation-level manipulations, highlighting a critical gap in current AI security readiness.
About the Speaker(s)
Tingwei Zhang is a third-year PhD student at Cornell Tech. He presented this work on "Self-interpreting Adversarial Images," which was a collaborative effort with his colleagues Colin, Jack, Eugene, and his advisor Vitali. His research focuses on the security implications of advanced AI models, particularly in understanding and mitigating adversarial threats against large language models and other machine learning systems. The work presented at USENIX Security underscores his commitment to exploring novel vulnerabilities and encouraging the development of more robust and secure AI technologies.
Reviews
Dr. Zero (Offensive Security Researcher) — STRONG ACCEPT
Solid, original research from a Cornell PhD student that identifies a genuinely underexplored attack surface: using imperceptible image perturbations as soft prompts to steer multimodal LLM interpretation rather than jailbreak it. The framing distinction — interpretation manipulation vs. capability unlocking vs. classic prompt injection — is the real contribution, and the transferability finding across commercial models elevates this above a lab curiosity.
Heather Calloway (CISO) — WEAK
Technically legitimate research on a real and underexplored attack surface — adversarial image perturbations that steer multimodal LLM interpretation without visible manipulation. But the talk stops at demonstration and never reaches the institutional questions that matter: who owns this risk, which deployments are already exposed, and what can a security team or AI governance function actually do about it today.
→ Top-rated talks at 34th USENIX Security Symposium (USENIX Security '25)
All talks from 34th USENIX Security Symposium (USENIX Security '25)