Found in Translation: A Generative Language Modeling Approach to Memory Access Pattern Attacks
Grace Jia (Yale)
34th USENIX Security Symposium (USENIX Security '25) · Day 3 · System Security 5: Securing Systems and Protocols
Overview
In the realm of confidential computing, where sensitive applications process data within hardware-protected environments, a new class of sophisticated side-channel attacks continues to emerge. This talk, "Found in Translation," presented by Grace Jia from Yale University, unveils a novel memory access pattern attack that leverages generative language modeling to infer private, object-level data from seemingly innocuous page-level access traces. The research, a collaborative effort with Alex Wong and Enrag Kandwal, demonstrates a practical and highly accurate method for an OS-level adversary to breach the confidentiality guarantees of trusted execution environments.
Key moments
- 0:00 Introduction to Found in Translation attack and target
- 2:00 Challenges in inferring object-level accesses for DLRM
- 4:00 Leveraging correlations between objects for identification
- 6:00 Threat model and adversary's auxiliary knowledge
- 7:00 Core insight: Applying language modeling to access patterns
- 8:00 Found in Translation (FIT) attack design overview
Found in Translation: A Generative Language Modeling Approach to Memory Access Pattern Attacks
Speakers: Grace Jia, PhD Student, Yale University (joint work with Alex Wong and Enrag Kandwal)
Conference: USENIX Security
YouTube: https://www.youtube.com/watch?v=wpazZkRMeWw
Overview
In the realm of confidential computing, where sensitive applications process data within hardware-protected environments, a new class of sophisticated side-channel attacks continues to emerge. This talk, "Found in Translation," presented by Grace Jia from Yale University, unveils a novel memory access pattern attack that leverages generative language modeling to infer private, object-level data from seemingly innocuous page-level access traces. The research, a collaborative effort with Alex Wong and Enrag Kandwal, demonstrates a practical and highly accurate method for an OS-level adversary to breach the confidentiality guarantees of trusted execution environments.
The core of the "Found in Translation" (Fit) attack lies in its innovative application of language modeling to discern complex correlations within memory access sequences. By treating these sequences as a "language," the attack can "translate" observed page accesses into predictions of the underlying sensitive data objects. This approach significantly outperforms prior attack methodologies by effectively addressing two critical challenges: the many-to-one mapping of multiple objects onto a single memory page, and the presence of arbitrary-length correlations between data accesses—factors previously considered significant hurdles for adversaries.
The significance of this work cannot be overstated. As confidential computing environments (CCEs) like Intel SGX and AWS Nitro Enclaves become increasingly prevalent for protecting sensitive workloads in untrusted cloud settings, understanding and mitigating such advanced side-channel attacks is paramount. "Found in Translation" exposes a fundamental leakage vector stemming from the operating system's necessary control over memory management and page table access bits, urging a re-evaluation of current security assumptions and the development of more robust correlation-hiding mechanisms to safeguard sensitive data against a powerful new class of adversaries.
Background
▶ Watch: Introduction to Found in Translation attack and target (0:00)
Confidential computing environments (CCEs) are designed to protect applications and their data from an untrusted software stack, including the operating system (OS) and hypervisor, in cloud settings. This protection is primarily achieved through trusted hardware that encrypts application memory pages and blocks unauthorized access from untrusted software components. Despite these robust hardware-level defenses, the OS retains crucial control over memory management, particularly the page table. When an application accesses an object in memory, dedicated hardware in the processor sets an access bit in the corresponding page table entry. This metadata is updated without OS intervention, but the OS can read these bits to perform essential functions like paging. While moving such OS functions into the CCE would enhance security, it would drastically inflate the trusted computing base (TCB), negatively impacting both security and performance.
This inherent visibility into page table access bits provides a powerful side channel for an OS-level adversary. Prior research has demonstrated that input-dependent memory accesses can reveal contents of encrypted data. Earlier attacks, such as fingerprinting objects with unique page accesses, could match specific objects to pages. However, these techniques often struggled with more complex scenarios. For instance, Markov modeling attacks, like IHOP, leverage correlations between consecutive accesses by building a Markov model of known access distributions. A critical limitation of these approaches is the assumption of a one-to-one mapping between objects and pages, which is often unrealistic in modern applications where multiple data objects reside on a single memory page.
Another common approach, frequency-based attacks (e.g., naive phase models), use histograms of accesses across pages to predict object-level accesses. While these methods can account for multiple objects per page, they fundamentally assume that accesses are independent, thereby ignoring the crucial presence of correlations within the data. The challenges for an adversary in these scenarios are twofold: first, with multiple objects on a page, the OS cannot directly discern which specific object was accessed; second, input data often contains arbitrary-length correlations that previous attacks have not effectively leveraged. The "Found in Translation" research directly addresses these limitations by introducing a method that can infer object-level accesses even when multiple objects share a page and when accesses exhibit complex, long-range correlations.
Key Findings
▶ Watch: Leveraging correlations between objects for identification (4:00)
The "Found in Translation" (Fit) attack represents a significant advancement in memory access pattern side-channel attacks within confidential computing environments. The primary key finding is the successful demonstration that generative language modeling can be effectively applied to memory access patterns, enabling an OS-level adversary to infer sensitive, object-level data from page-level access traces with high accuracy. This novel approach overcomes fundamental limitations of prior attacks, specifically the inability to distinguish between multiple objects on a single page and to leverage arbitrary-length correlations between accesses.
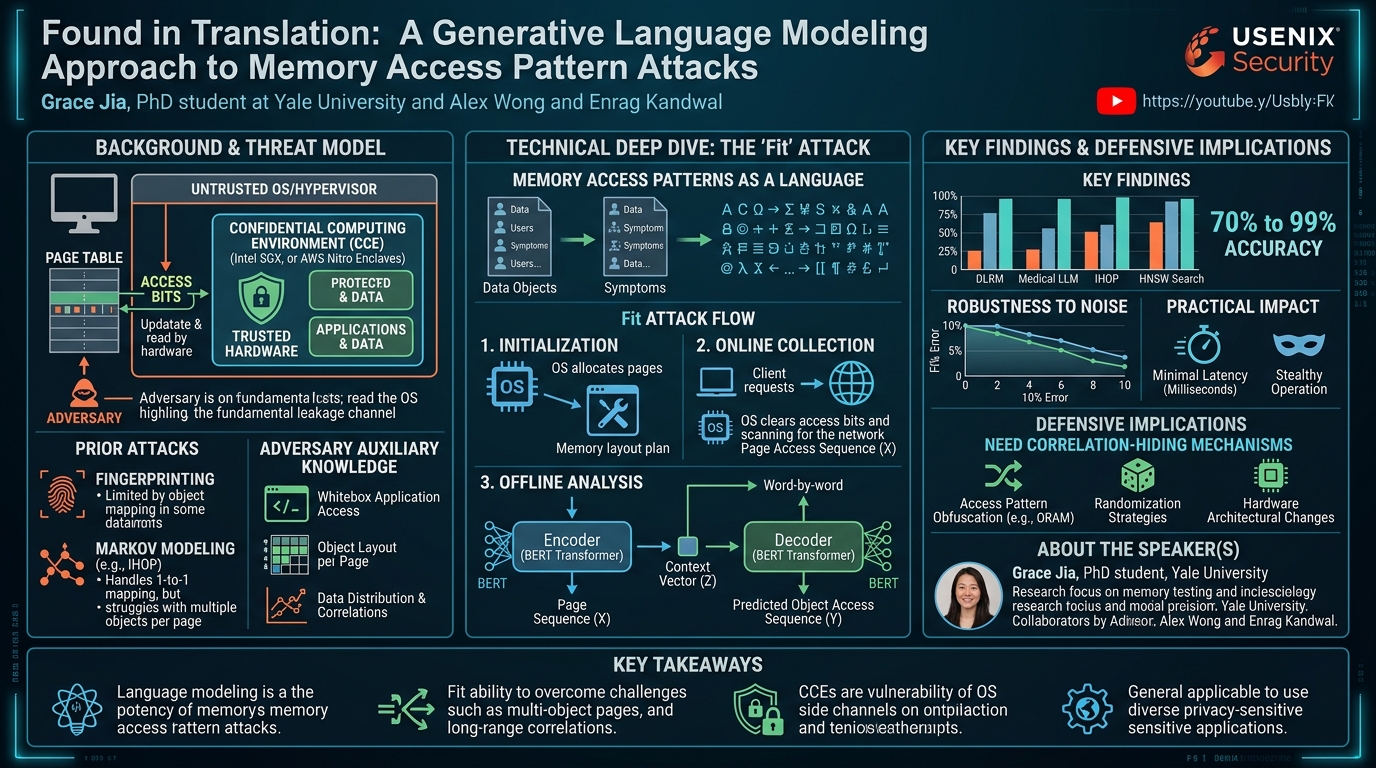
The research established that Fit achieves 70% to 99% accuracy in correctly predicting object accesses across a diverse range of real-world, privacy-sensitive applications. These applications include a Deep Learning Recommendation Model (DLRM), a Medical Large Language Model (LLM), and a Hierarchical Navigable Small Worlds (HNSW) semantic search algorithm. This broad applicability underscores the generalizability and potency of the language modeling approach. In comparative evaluations, Fit significantly outperformed existing baselines: Naive Bayes, which relies on frequency analysis, and IHOP, a Markov-based approach. Naive Bayes struggled due to its lack of correlation awareness, while IHOP suffered considerably from the presence of multiple objects per page, a common scenario in modern memory layouts.
Furthermore, the study revealed the practical robustness of the Fit attack. It demonstrated resilience to real-world noise, maintaining strong performance even with injected error rates up to 10% in page access identification, far exceeding the approximately 1% error observed in online collection. This robustness is attributed to the model's ability to leverage the context of the full access sequence for predictions, making it less susceptible to minor, localized errors. Crucially, the online phase of the attack, which involves monitoring page accesses, introduced only milliseconds of latency per request. Such minimal overhead is often imperceptible to users and can be easily masked by network jitter or integrated into existing OS memory management practices like tiered memory, making the attack stealthy and difficult to detect through performance monitoring alone.
In essence, "Found in Translation" proves that by treating memory access patterns as a language, an adversary can "translate" observable page-level events into highly specific, object-level private information, effectively bypassing the memory encryption protections of state-of-the-art confidential computing hardware.
Technical Deep Dive
▶ Watch: Threat model and adversary's auxiliary knowledge (6:00)
The "Found in Translation" (Fit) attack is predicated on a sophisticated threat model and a multi-phase methodology centered around deep generative language modeling. The adversary is an honest-but-curious cloud provider at the OS level. This adversary is prevented from directly accessing or modifying application data within the confidential computing environment (CCE) but can observe side-channel leakage—specifically, page access patterns via the page table access bits. The adversary also possesses auxiliary knowledge, which is often readily available in cloud environments:
- Whitebox access to the targeted application: Many widely deployed cloud applications, such as DLRM, are open-source.
- Layout of objects per page: The OS controls memory allocations, thus it knows how objects are laid out in memory.
- Distribution of plaintext data and its correlations: This joint distribution of features (e.g., user demographics, shopping habits) is often widely accessible information.
The core insight of Fit is to treat memory access patterns as a language. Just as a language model captures the probability distribution of words in a sentence, Fit models the probability distribution of sensitive object access sequences (Y) conditioned on observable page access sequences (X). This allows the model to harness context to disambiguate between ambiguous page accesses, much like how the context of "right hand" versus "that is right" disambiguates the meaning of "right" in English. The attack is structured into three distinct phases:
1. Initialization
When the targeted application requests memory from the OS, the adversary, using its knowledge of the application's code, strategically allocates specific page regions to its objects of interest. This step is crucial for mapping the known object layout to observable memory pages.
2. Online Collection
As client requests arrive over the network, the OS identifies each request via network system calls. For each request:
- The adversary clears the page table access bits for the monitored pages.
- The application processes the request, naturally accessing various memory pages.
- The OS periodically interrupts the application to scan and clear the access bits.
- The pages that had their access bits set before being cleared form the page access sequence (X) for that request.
This process repeats for all incoming requests, building a dataset of observed page access sequences. The duration of this phase can range from minutes to hours, depending on the application's activity.
3. Offline Analysis
This phase involves training and inference using the language model:
- Training Data Generation: The adversary executes the whiteboxed application on simulated requests. These simulations follow the known data distribution, providing ground truth pairs of page access sequences (X) and their corresponding object access sequences (Y).
- Language Model Training: The generated (X, Y) pairs are used to train a deep generative language model. The architecture employed is a recurrent encoder-decoder model, specifically leveraging the BERT transformer model for both the encoder and decoder.
- The encoder network processes the input page access sequence (X) element by element, updating its internal state and outputting a context vector (Z), which is a vector representation of the input sequence.
- The decoder network takes this context vector (Z) and generates object-level accesses (Y) one by one. Each new output influences the subsequent prediction, allowing the model to build a coherent object access sequence.
- BERT's transformer architecture is particularly effective due to its ability to process sequences in parallel and learn global dependencies between X and Y during training. The use of pre-trained weights for language prediction significantly accelerates training convergence compared to randomly initialized weights.
- Inference: Once trained, the model is used to run inference on the page access sequences (X) collected during the online phase, predicting their underlying object access sequences (Y).
The combination of the OS's privileged position, detailed auxiliary knowledge, and the advanced contextual understanding provided by a generative language model like BERT allows Fit to accurately "translate" noisy, page-level observations into precise, object-level sensitive information, even in the presence of complex memory layouts and data correlations.
Demo / Proof of Concept
▶ Watch: Core insight: Applying language modeling to access patterns (7:00)
The "Found in Translation" attack was rigorously evaluated on three real-world, privacy-sensitive applications, demonstrating its practical efficacy across diverse use cases. These applications were run within two prominent confidential computing environments: AWS Nitro Enclaves and Intel SGX Enclaves on Azure.
- Deep Learning Recommendation Model (DLRM): This application, a running example throughout the talk, takes user features (e.g., city, items in shopping cart) as input and predicts a click-through rate for an ad. For each categorical feature, DLRM performs an embedding table lookup, which directly leaks the feature's value. The evaluation used real-life data from Criteo display ads, with 1 million sample sequences for training and 100,000 for evaluation.
- Medical Large Language Model (LLM): This application takes patient symptoms as prompts and responds with a diagnosis. Similar to DLRM, it performs an embedding table lookup for each token in the prompt, potentially revealing sensitive medical information. User prompts were generated from the medical diagnosis benchmark DDX+.
- Hierarchical Navigable Small Worlds (HNSW): A state-of-the-art semantic search algorithm often used in vector databases containing sensitive information like biometrics or face images. For each search query, HNSW traverses a multi-layer graph index, which reveals the nearest neighbors of the queried vector. The dataset for this use case was the SIFT image search benchmark.
The online phase of the attack was mounted on executions within both Nitro and SGX enclaves to collect page access sequences. For offline analysis, Fit's performance was compared against two baselines:
- Naive Bayes: Representing frequency analysis attacks.
- IHOP: Representing Markov-based approaches.
Fit's training and inference were performed on Nvidia GPUs, while baselines ran on AMD CPUs. The primary performance metric was the normalized Hamming distance between the predicted object sequence and the ground truth target sequence, quantifying incorrect access predictions per sequence.
The results consistently showed Fit's superior performance, predicting 70% to 99% of object accesses correctly across all applications and environments. Naive Bayes was significantly less successful due to its inability to account for correlations, while IHOP suffered substantially from the common scenario of multiple objects residing on a single page. Fit's ability to learn both the many-to-one relationship between objects and pages and arbitrary-length correlations was key to its success.
Practical considerations were also evaluated:
- Sensitivity to Error: The online phase typically observed about 1% incorrect page access identifications (false positives from hardware pre-fetching/software metadata access, false negatives from background processes clearing bits). Fit's accuracy did not degrade significantly even with injected error rates up to 10%, demonstrating its robustness due to leveraging full sequence context.
- Latency Overhead: Page tracking introduced only milliseconds of latency per request. This low overhead can be masked by network jitter or integrated into OS-level memory management techniques like tiered memory, making the attack difficult to detect. Offline analysis time, while polynomial in dataset size, is less critical as it does not impact live service.
The successful demonstration across diverse applications and CCEs, coupled with its robustness and low overhead, firmly establishes "Found in Translation" as a practical and potent threat to the confidentiality of data processed within trusted execution environments.
Defensive Implications
▶ Watch: Found in Translation (FIT) attack design overview (8:00)
The "Found in Translation" attack presents profound defensive implications for the design and deployment of confidential computing environments. The research unequivocally demonstrates that current CCEs, despite their robust memory encryption, remain vulnerable to sophisticated OS-level side-channel attacks that exploit memory access patterns. The fundamental leakage stems from the OS's legitimate, hardware-assisted visibility into page table access bits, a mechanism essential for memory management but now proven to be a potent information channel.
Defenders can no longer solely rely on memory encryption to protect sensitive data within CCEs. The attack highlights the critical need for correlation-hiding mechanisms to prevent adversaries from inferring object-level information from page-level access patterns. Simply encrypting memory pages is insufficient if the pattern of access to those pages reveals the underlying data.
Potential defensive strategies, though challenging to implement effectively, could include:
- Access Pattern Obfuscation: Techniques to randomize or obscure memory access patterns, such as Oblivious RAM (ORAM). However, ORAM typically introduces significant performance overhead, making it impractical for many real-world applications.
- Memory Layout Randomization: Dynamically changing the layout of objects on pages or the mapping of pages to physical memory could make it harder for the adversary to build accurate models of object-to-page relationships. This would complicate the initialization phase of the Fit attack.
- Page Size Variation: As mentioned in the future work, studying sensitivity to varying page sizes could inform defensive strategies. Larger or dynamically changing page sizes might aggregate more objects, increasing ambiguity, but could also simplify tracking if not carefully managed.
- Hardware-Assisted Access Bit Management: Rethinking how page table access bits are exposed to the OS, or whether the OS needs direct access to them for confidential memory regions, could be a long-term hardware-level mitigation. This would require significant architectural changes.
- Application-Specific Mitigations: For highly sensitive applications, developers might need to design their memory access patterns to be less input-dependent or to access irrelevant data to introduce noise, akin to traditional side-channel countermeasures. However, this is complex and error-prone.
- Secure Memory Allocation Policies: The OS, when allocating memory for CCEs, could employ strategies that actively break correlations between object groups or place unrelated objects on the same page to increase ambiguity, making the "translation" task for the language model much harder.
Ultimately, the "Found in Translation" attack underscores that the security of confidential computing is not just about protecting data at rest or in transit, but also about protecting the patterns of data access during computation. Defenders must now consider a holistic approach that includes architectural changes, robust obfuscation techniques, and a deeper understanding of application-level access behaviors to truly secure sensitive workloads in the cloud.
Key Takeaways
- Language modeling is a potent new weapon for memory access pattern attacks: The "Found in Translation" (Fit) attack demonstrates that deep generative language models, specifically BERT, can effectively "translate" page-level memory access traces into sensitive object-level information.
- Fit overcomes critical limitations of prior attacks: It successfully addresses the challenges of multiple objects sharing a single memory page (many-to-one mapping) and arbitrary-length correlations between data accesses, which previously hindered effective inference.
- Confidential computing environments (CCEs) are vulnerable to OS-level side channels: Despite hardware-backed memory encryption, the OS's legitimate access to page table access bits provides a fundamental leakage channel that can be exploited by sophisticated adversaries.
- Real-world, privacy-sensitive applications are susceptible: DLRM, Medical LLMs, and HNSW search algorithms were shown to be vulnerable, achieving 70-99% accuracy in object-level data inference, highlighting the broad applicability of the attack.
- The attack is practical, robust, and stealthy: Fit exhibits high accuracy, robustness against page tracking errors (up to 10%), and introduces minimal, maskable latency (milliseconds), making it a significant and practical threat in cloud environments.
- Defenders urgently need correlation-hiding mechanisms: Current CCE designs require fundamental re-evaluation, and new defensive strategies, such as architectural changes or sophisticated obfuscation techniques, are necessary to prevent the leakage of access patterns.
About the Speaker(s)
Grace Jia is a PhD student at Yale University. Her work focuses on novel security vulnerabilities and attack methodologies, particularly in the realm of memory access patterns and confidential computing. The "Found in Translation" research is a collaborative effort with Alex Wong and her advisor, Enrag Kandwal, highlighting her contributions to identifying and exploiting subtle side-channel leakages in modern computing architectures.
Reviews
Dr. Zero (Offensive Security Researcher) — STRONG ACCEPT
Solid academic research that meaningfully advances the SGX/enclave side-channel attack surface by grafting sequence-to-sequence language modeling onto page-access inference — a genuinely novel framing that outperforms Markov and frequency baselines on real workloads. The 70-99% accuracy range on DLRM, medical LLM, and HNSW across both Nitro and SGX is the kind of empirical breadth that separates real papers from toy demos. Doesn't quite crack the 5-star ceiling because the defensive section is thin and the architectural choices (BERT encoder-decoder) could use harder justification against simpler sequence models.
Heather Calloway (CISO) — WEAK
Technically credible academic research that advances the state of knowledge on side-channel attacks against confidential computing. But the talk stops at the exploit — it tells operators that CCEs are broken without telling them what to do about it, and the defensive section amounts to a research wishlist, not an action plan.
→ Top-rated talks at 34th USENIX Security Symposium (USENIX Security '25)
All talks from 34th USENIX Security Symposium (USENIX Security '25)