Shesha: Multi-head Microarchitectural Leakage Discovery in new-generation Intel Processors
Anirban Chakraborty
33rd USENIX Security Symposium · Day 1 · USENIX Security '24 · USENIX Security '24
Overview
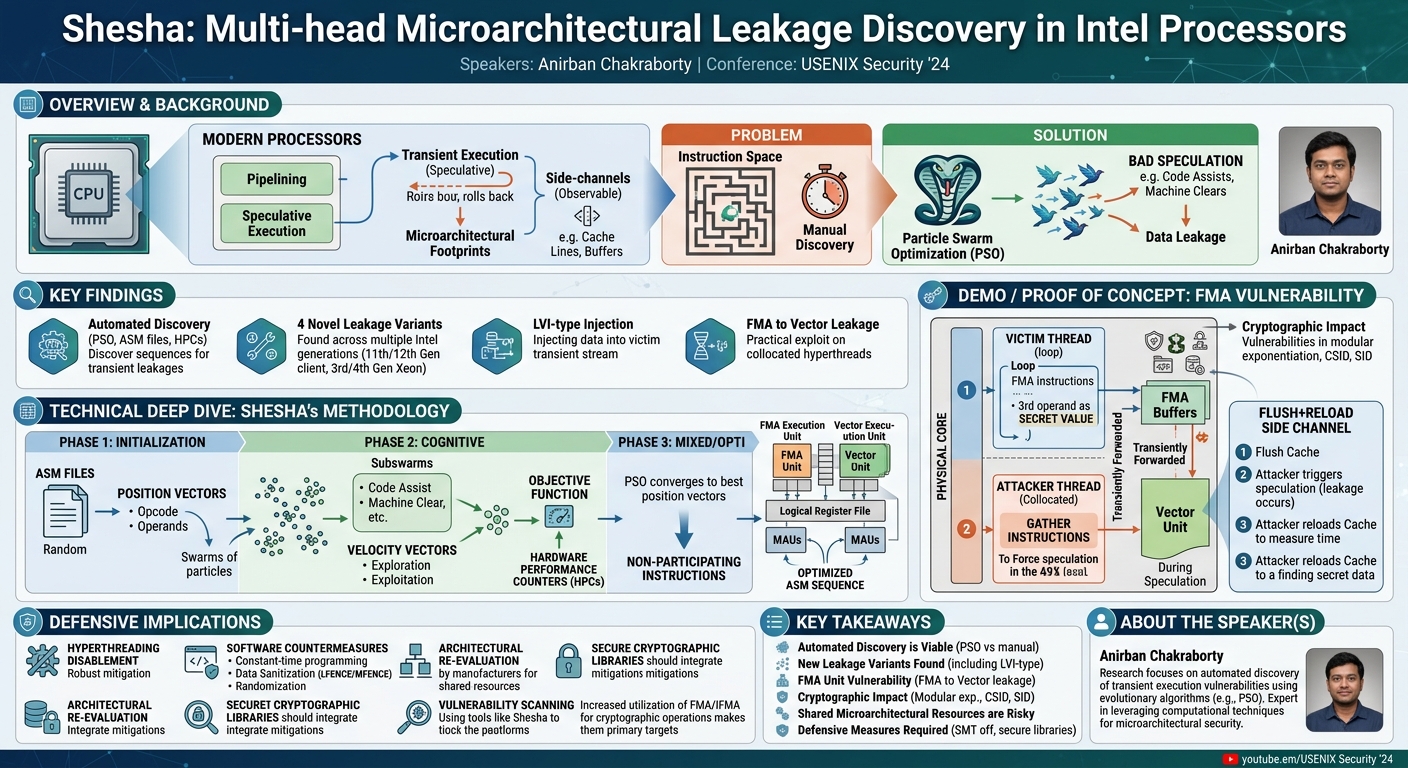
This talk introduces Shesha, an innovative automated framework designed to discover novel microarchitectural leakage vulnerabilities in modern Intel processors. Given the increasing complexity of processor designs and the subtle nature of transient execution side channels, manual discovery of these vulnerabilities is an arduous and time-consuming task, often requiring specialized expertise and sophisticated mechanisms. Shesha addresses this challenge by leveraging Particle Swarm Optimization (PSO), an evolutionary algorithm, to systematically explore the vast instruction sequence space and identify specific sequences that trigger "bad speculation" events, which can subsequently lead to data leakage.
Key moments
- 0:00 Introduction to transient execution and microarchitectural leakage
- 1:20 Shesha's goal: Automating transient leakage vulnerability discovery
- 2:05 Shesha's core methodology: Particle Swarm Optimization
- 3:50 Shesha's three-phase architecture for instruction generation
- 5:00 Shesha's novel transient leakage discoveries on Intel
- 6:00 Practical case study: Fused Multiply Add (FMA) instructions
- 7:30 FMA speculative forwarding hypothesis and experiment design
Shesha: Multi-head Microarchitectural Leakage Discovery in new-generation Intel Processors
Speakers: Anirban Chakraborty
Conference: USENIX Security '24
YouTube: https://www.youtube.com/watch?v=6lkLOwac84I
Overview
This talk introduces Shesha, an innovative automated framework designed to discover novel microarchitectural leakage vulnerabilities in modern Intel processors. Given the increasing complexity of processor designs and the subtle nature of transient execution side channels, manual discovery of these vulnerabilities is an arduous and time-consuming task, often requiring specialized expertise and sophisticated mechanisms. Shesha addresses this challenge by leveraging Particle Swarm Optimization (PSO), an evolutionary algorithm, to systematically explore the vast instruction sequence space and identify specific sequences that trigger "bad speculation" events, which can subsequently lead to data leakage.
The core problem Shesha tackles is the inherent difficulty in finding instruction sequences that cause processors to enter transient execution states, where instructions execute speculatively but are later rolled back. While these rolled-back instructions have no architectural effect, they leave detectable microarchitectural footprints that can be exploited for sensitive data leakage. The research specifically focuses on "bad speculation" events, a term coined by Intel, which encompass scenarios like code assists and machine clears that occur when the processor encounters exceptional conditions and attempts to recover.
Anirban Chakraborty presents Shesha as a critical tool for automating this discovery process, moving beyond the traditional, labor-intensive methods. The work demonstrates not only the efficacy of an automated approach in uncovering new transient leakage variants but also provides a practical proof-of-concept exploit targeting Fused Multiply-Add (FMA) instructions, which are widely used in performance-critical applications, including cryptography. This research is highly significant for processor architects, security researchers, and software developers, as it uncovers new attack surfaces and provides a methodology for proactive vulnerability discovery.
Background
▶ Watch: Introduction to transient execution and microarchitectural leakage (0:00)
Modern processors rely heavily on pipelining and speculative execution to achieve high performance. Pipelining allows multiple instructions to be in different stages of execution concurrently. Speculative execution takes this a step further by executing instructions before their dependencies are fully resolved or before the outcome of a branch is known. If a speculation turns out to be incorrect, the processor must roll back the speculative execution, discarding its architectural effects on registers and memory. However, these transient executions can leave residual traces in the processor's microarchitectural state, such as cache lines, branch predictors, or execution unit buffers. These traces can then be observed by an attacker using side-channel attacks to infer sensitive data.
The phenomenon of microarchitectural leakage has been the subject of extensive research following the discovery of Spectre and Meltdown, revealing numerous attack vectors across various processor components. The proliferation of such vulnerabilities stems from the inherent complexity of modern processor design, where optimizations often introduce unintended side channels. Discovering these vulnerabilities manually is exceptionally challenging due to the intricate interplay of instructions, microarchitectural events, and timing. It requires deep understanding of processor internals, reverse engineering skills, and often, highly sophisticated experimental setups.
This work specifically targets "bad speculation" events, a category of transient execution scenarios defined by Intel, which include code assists and machine clears. These events occur when the processor encounters situations that require internal state adjustments or recovery mechanisms, potentially leading to transient windows where data can be leaked. The motivation behind Shesha is to automate the identification of specific instruction sequences that reliably trigger these bad speculation events, thereby streamlining the discovery of new transient leakage variants. Prior research often required a human expert to hypothesize potential leakage points and meticulously craft instruction sequences to test them. Shesha aims to replace this manual, iterative process with an intelligent, automated search strategy.
Key Findings
▶ Watch: Shesha's core methodology: Particle Swarm Optimization (2:05)
Shesha's automated discovery process yielded significant results, demonstrating its efficacy in uncovering novel microarchitectural vulnerabilities in modern Intel processors. The primary key findings include:
- Automated Vulnerability Discovery: The successful application of Particle Swarm Optimization (PSO) to automatically generate instruction sequences that trigger bad speculation events and subsequent transient leakages. This represents a significant advancement over manual, ad-hoc discovery methods.
- Four Novel Transient Leakage Variants: Shesha successfully identified four distinct, novel transient leakage variants across various Intel processor generations, including 12th and 11th generation client systems, and 3rd and 4th generation Xeon systems. These variants were triggered by specific, optimized instruction sequences discovered by the tool.
- LVI-type Injection: Some of the newly discovered leakage variants also exhibited characteristics similar to Load Value Injection (LVI), indicating potential for injecting arbitrary data into a victim's transient execution stream, a severe form of transient execution attack.
- FMA Unit to Vector Unit Leakage: The most practically significant finding, and the focus of the detailed exploit, involves a novel leakage path between the Fused Multiply-Add (FMA) execution unit and the Vector execution unit. This leakage occurs on collocated hyperthreads, where data from FMA operations can be transiently forwarded to the Vector unit during speculative execution.
- Shared Buffers Hypothesis: The successful FMA-to-Vector unit leakage experiment strongly supports the hypothesis that these distinct execution units (FMA and Vector) share common internal buffers, despite having separate execution pipelines. This shared resource becomes a critical pathway for transient data leakage.
- Impact on Cryptographic Applications: The FMA leakage was demonstrated to have direct implications for cryptographic implementations that utilize FMA or Integer Fused Multiply-Add (IFMA) instructions for performance, such as modular exponentiation (specifically Montgomery multiplication), CSID, and SID.
These findings underscore the ongoing challenges in securing microarchitectural designs and highlight the power of automated approaches in uncovering subtle yet critical vulnerabilities.
Technical Deep Dive
▶ Watch: Shesha's three-phase architecture for instruction generation (3:50)
Shesha's core innovation lies in its use of Particle Swarm Optimization (PSO) to automate the search for vulnerability-triggering instruction sequences. PSO is a metaheuristic optimization algorithm inspired by the social behavior of bird flocking or fish schooling. It operates on a population of candidate solutions, called "particles," which move through the search space.
The process begins with Shesha's three-phase methodology:
- Initialization Phase (03:50):
- Shesha starts by generating a set of randomly configured Assembly (ASM) files. Each file consists of
Ninstructions, whereNcan be substantial (e.g., 40-50 instructions or more). - These ASM files are then transformed into position vectors. A position vector is a mathematical encoding of an instruction sequence, representing the instruction opcodes and their associated operands. This encoding allows the instruction sequences to be treated as mathematical entities that can be manipulated and optimized by the PSO algorithm. The initial particles in the swarm are essentially these randomly generated instruction sequences.
- Cognitive Phase (04:00):
- This phase introduces velocity vectors, which govern the movement of each particle in the search space. A particle's velocity is influenced by its own best-found position (cognitive component) and the best-found position of the entire swarm (social component). This mechanism facilitates the sharing of information and knowledge among particles.
- Crucially, Shesha employs subswarms. Instead of a single large swarm, multiple smaller subswarms are created, with each subswarm specifically configured to focus on searching for instruction sequences that trigger a specific type of bad speculation event. For example, one subswarm might target "code assists" while another focuses on "machine clears." This parallel search strategy allows for more efficient exploration of different vulnerability types.
- The objective function for PSO is derived from hardware performance counters (HPCs). These counters track the occurrence of different types of bad speculation events within the processor. The goal of the PSO is to find instruction sequences (position vectors) that maximize the count of a target bad speculation event. This direct feedback from hardware is what makes Shesha hardware-agnostic in its search.
- PSO's key advantages – exploration (random search by individual particles) and exploitation (collective intelligence through swarm communication) – are critical here. Exploration ensures that new, uncharted areas of the instruction space are investigated, while exploitation ensures that promising areas are thoroughly refined and optimized.
- Mixed/Optimization Phase (04:40):
- Once the PSO algorithm has converged or run for a predetermined number of iterations, it produces a set of instruction sequences that are effective at triggering bad speculation events.
- In this final phase, Shesha optimizes these sequences by removing "non-participating instructions" – instructions that do not contribute to triggering the desired bad speculation event. This pruning results in a concise and highly optimized ASM sequence, making the discovered vulnerabilities easier to analyze and reproduce.
The practical application of Shesha led to the discovery of four novel transient leakage variants. The most significant of these, detailed in the talk, involved Fused Multiply-Add (FMA) instructions. FMA instructions are single instructions that perform two arithmetic operations, typically a multiplication followed by an addition or subtraction (e.g., (A * B) + C). They are crucial for high-performance computing, especially in scientific and cryptographic applications.
The architectural analysis, informed by Intel patents, highlights that FMA execution units, like other generic execution units, have a front-end (instruction decoding, micro-op generation, branch prediction) and a back-end (renaming, allocation, retirement, physical register files). A critical component identified between the FMA execution unit and the memory hierarchy (cache) are Memory Access Units (MAUs). These MAUs act as buffers, designed to reduce memory access latency, especially since FMA instructions often support memory operands directly.
The researchers hypothesized two potential speculative forwarding paths:
- From MAUs to the FMA execution unit.
- Between the FMA execution unit and the Vector execution unit (e.g., AVX, SSE units). This second hypothesis was particularly compelling because, despite being separate hardware units, the FMA and Vector execution units are known to share the same logical register file. This shared logical resource creates a potential microarchitectural link that could be exploited during transient execution.
While the first hypothesis (MAU to FMA unit forwarding) did not yield results, likely due to the transient window being insufficient to encompass all operations, the second hypothesis proved fruitful, leading to the practical exploit demonstrated.
Demo / Proof of Concept
▶ Watch: Practical case study: Fused Multiply Add (FMA) instructions (6:00)
The most compelling demonstration of Shesha's findings centered on the transient leakage between the FMA execution unit and the Vector execution unit on Intel processors. This proof-of-concept (PoC) highlighted a critical vulnerability arising from shared microarchitectural resources.
The experimental setup involved two collocated hyperthreads, one acting as the victim and the other as the attacker:
- Victim Thread: The victim thread was designed to execute FMA instructions within a tight loop. Crucially, the third operand of the FMA instruction was programmed to a predetermined, secret value. This simulates a scenario where sensitive data (like a cryptographic key component or intermediate result) is being processed by FMA operations.
- Attacker Thread: The attacker thread, running on a collocated hyperthread, aimed to force the AVX (Vector) execution unit into a state of transient execution. To achieve this, the researchers leveraged gather instructions, a technique previously identified as capable of inducing speculation in AVX units, notably linked to vulnerabilities like Downfall (CVE-2022-40982). By executing specific gather instructions, the attacker could create a transient window within the Vector unit.
The core finding was that when the attacker successfully forced the AVX execution unit into speculation, data from the victim's FMA execution unit was transiently forwarded to the Vector execution units. This occurred despite FMA and Vector operations typically being handled by distinct hardware units. The leakage strongly suggested that these two execution units, while logically separate, share common internal buffers in hardware. During the transient execution window initiated by the attacker, the speculative operations in the Vector unit could access and expose data that was momentarily present in these shared buffers, originating from the FMA unit.
To extract the leaked data, a generic flush+reload side channel technique was employed. This method involves:
- Flushing a specific cache line associated with the leaked data from the cache.
- Triggering the transient execution and potential data forwarding.
- Reloading the cache line and measuring the access time. A fast access time indicates the data was brought back into the cache by the transient operation, thus confirming leakage.
The successful demonstration of this FMA-to-Vector unit leakage, coupled with the flush+reload side channel, provided concrete evidence of a new microarchitectural vulnerability. It revealed how shared logical register files and underlying shared buffers could become conduits for sensitive data leakage during transient execution, even between seemingly distinct execution units. This PoC validated Shesha's ability not only to find triggering instruction sequences but also to pinpoint practical leakage paths.
Defensive Implications
▶ Watch: FMA speculative forwarding hypothesis and experiment design (7:30)
The discovery of transient leakage from FMA and IFMA (Integer Fused Multiply-Add) units, particularly its impact on collocated hyperthreads, carries significant defensive implications, especially for security-critical applications like cryptography.
The talk highlights that FMA and IFMA instructions are increasingly utilized to accelerate cryptographic operations, such as Montgomery multiplication within modular exponentiation algorithms. These algorithms form the backbone of many public-key cryptosystems. The leakage demonstrated implies that if a cryptographic routine uses IFMA instructions to process sensitive inputs (e.g., the AI multiplicate in modular exponentiation) on one hyperthread, a malicious process on a collocated hyperthread can force speculation in the vector unit and transiently siphon off this sensitive data.
Specifically, the research showed similar leakage on implementations of CSID (Commutative Supersingular Isogeny Diffie-Hellman) and SID (Supersingular Isogeny Diffie-Hellman) – two post-quantum cryptographic schemes – which also rely on IFMA instructions for performance. This means that even next-generation cryptographic algorithms designed to withstand future quantum attacks could be vulnerable to current-generation microarchitectural side channels.
For defenders, these findings necessitate a re-evaluation of how cryptographic primitives are implemented and deployed, especially in multi-tenant or shared-resource environments (e.g., cloud computing, virtualized environments). Key defensive strategies include:
- Hyperthreading Disablement: The most robust, albeit performance-impacting, mitigation is to disable hyperthreading (Intel's Simultaneous Multi-Threading or SMT). This prevents logical cores from sharing physical execution resources, eliminating the collocated hyperthread scenario crucial for this attack.
- Software Countermeasures: For scenarios where hyperthreading cannot be disabled, software-based mitigations similar to those developed for other transient execution attacks might be necessary. This could involve:
- Constant-time programming: Ensuring that cryptographic operations execute in a timing-independent manner, regardless of secret values. However, microarchitectural leakages often bypass traditional constant-time guarantees.
- Data sanitization: Using instructions like
LFENCEorMFENCEto serialize execution and clear speculative buffers before and after processing sensitive data. The efficacy of these fences against all transient windows needs careful validation for this specific FMA leakage. - Randomization: Introducing randomness into sensitive data or its processing to obscure actual values, though this can be complex for arithmetic operations.
- Architectural Re-evaluation: Processor manufacturers need to continue scrutinizing their microarchitectural designs for shared resources that can act as transient leakage channels. The discovery of shared buffers between FMA and Vector units, despite distinct logical functions, points to a broader design challenge in achieving strong isolation at the microarchitectural level.
- Secure Cryptographic Libraries: Developers of cryptographic libraries (e.g., OpenSSL, Libsodium) should integrate mitigations for these types of attacks, potentially offering configurable options for users to trade performance for enhanced security (e.g., disabling IFMA/FMA acceleration when SMT is enabled).
- Vulnerability Scanning: Tools like Shesha offer a proactive way for organizations to test their critical infrastructure and software for similar undiscovered microarchitectural vulnerabilities, going beyond known CVEs.
The continuous discovery of such subtle leakages emphasizes that microarchitectural security remains a critical, evolving challenge, requiring a multi-faceted approach involving hardware design, operating system hardening, and secure software development practices.
Key Takeaways
- Automated Discovery is Viable: Shesha demonstrates that Particle Swarm Optimization (PSO) can effectively automate the discovery of novel microarchitectural transient execution vulnerabilities, reducing reliance on manual, labor-intensive methods.
- New Leakage Variants Found: The tool identified four novel transient leakage variants in new-generation Intel processors, including some exhibiting LVI-type injection characteristics.
- FMA Unit Vulnerability: A significant practical finding is the transient leakage of data from the FMA execution unit to the Vector execution unit on collocated hyperthreads, due to shared internal buffers.
- Cryptographic Impact: This FMA leakage directly impacts the security of cryptographic implementations (e.g., modular exponentiation, CSID, SID) that leverage FMA/IFMA instructions for performance.
- Shared Microarchitectural Resources are Risky: The vulnerability highlights that shared microarchitectural resources, even between functionally distinct execution units, can create unintended side channels for sensitive data leakage.
- Defensive Measures Required: Mitigations like disabling hyperthreading, re-evaluating cryptographic implementations, and potentially software-based countermeasures are crucial to protect against these new attack vectors.
About the Speaker(s)
Anirban Chakraborty is a speaker at USENIX Security '24, where he presented the work on Shesha. His research focuses on the complex and challenging domain of microarchitectural security, particularly the automated discovery of transient execution vulnerabilities in modern processors. His expertise lies in leveraging advanced computational techniques, such as evolutionary algorithms like Particle Swarm Optimization, to address fundamental security problems in hardware design.
Reviews
Dr. Zero (Offensive Security Researcher) — MUST SEE
This research introduces Shesha, a groundbreaking PSO-based framework for automated discovery of microarchitectural transient execution vulnerabilities, uncovering novel FMA-to-Vector unit leakage. This critical finding directly impacts cryptographic implementations, demanding immediate attention from processor architects and security engineers.
Heather Calloway (CISO) — STRONG ACCEPT
This research introduces Shesha, an automated framework that successfully identified novel microarchitectural leakage, including a critical FMA-to-Vector unit vulnerability impacting cryptographic operations. It provides clear evidence of ongoing processor design risks and offers concrete mitigations, particularly emphasizing the need to re-evaluate hyperthreading policies for sensitive workloads.